


Site Reliability Engineering (SRE): A Complete Guide to Principles, Practices, and Benefits
DevOps Team
Last Updated: Nov 05, 2026 Total Views: 88
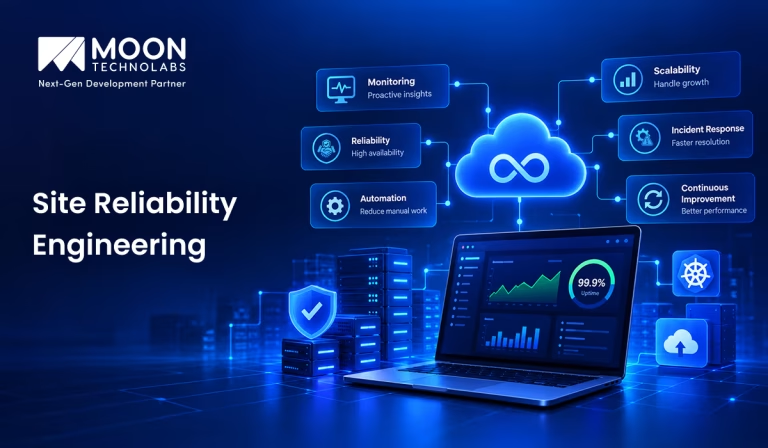
Table of Content


Blog Summary:
Site Reliability Engineering (SRE) helps organizations build reliable, scalable, and resilient software systems through automation, monitoring, and data-driven decision-making. This guide explores core SRE principles, practical implementation strategies, and key benefits, including reduced downtime, faster incident response, improved system performance, and a better balance between software delivery speed and operational stability.
Table of Content
Modern applications don’t fail just because of bad code. Sometimes, a deployment introduces an unexpected bug, a traffic spike overwhelms a service, or a small infrastructure issue triggers a chain reaction across the system. The real challenge isn’t just fixing these problems—it’s preventing them from becoming recurring incidents. That’s where Site Reliability Engineering (SRE) comes in.
By applying software engineering to operational challenges, SRE helps teams move beyond reactive firefighting toward measurable, sustainable reliability. Instead of treating uptime as a vague goal, SRE gives teams concrete ways to measure reliability, manage risk, and decide when to prioritize stability over new releases.
What is Site Reliability Engineering (SRE)?
SRE applies software engineering principles to operational challenges, helping businesses release updates without compromising system stability. It focuses on making applications easier to monitor, maintain, and recover when unexpected failures affect production environments.
Rather than repeatedly fixing the same issues, SRE teams investigate recurring failures, track service performance, and automate routine operational tasks. Reliability targets and real-world system data help engineers identify bottlenecks, plan infrastructure capacity, and determine when changes are needed to maintain consistent performance.
These practices are particularly valuable in cloud application development, where systems must handle fluctuating traffic, interconnected services, and evolving user expectations. By incorporating monitoring, automated recovery, and reliability testing from the start, teams can catch potential weaknesses early and build applications that stay dependable as business requirements change.
Role of SRE in Cloud Infrastructure and Operations
Explore how SRE keeps cloud infrastructure stable during traffic spikes, reduces manual operational work, prevents recurring failures, and minimizes service disruptions:
Cloud Infrastructure Monitoring
A cloud application can appear healthy at the server level while users experience failed logins or slow transactions. Effective monitoring connects infrastructure metrics with application behavior, helping teams correlate incidents, identify failing dependencies, and trace problems across microservices before outages spread.
Performance and Capacity Management
Unexpected traffic growth can overwhelm databases, exhaust connection pools, or slow API responses. Capacity planning uses historical usage, workload forecasts, and stress-test results to identify these limits early, ensuring sufficient resources are available without maintaining expensive excess capacity.
Infrastructure as Code (IaC)
Manual infrastructure changes often create inconsistent environments and hard-to-reproduce failures. IaC addresses this by defining networks, compute resources, permissions, and storage in reusable configurations, enabling teams to review changes, track modifications, and recreate reliable environments across multiple cloud accounts.
Automated Scaling and Resource Optimization
Cloud workloads rarely maintain consistent resource requirements throughout the day. Scaling policies respond to demand by adjusting the number of application instances or container replicas. At the same time, rightsizing recommendations and scheduled shutdowns for non-production environments help reduce idle capacity, control cloud expenditure, and maintain acceptable performance.
High Availability and Disaster Recovery
A regional cloud outage, corrupted database, or accidental configuration change can interrupt critical business operations. Resilient architectures use redundant services, replicated data, tested backups, and documented recovery procedures to restore functionality, limit data loss, and keep essential applications available during infrastructure failures.
Get expert guidance on SLOs, automation, incident management, and observability to build dependable systems without slowing development.
Incident Management and Root Cause Analysis in SRE
Understand how SRE teams respond to production incidents, trace failures to their underlying causes, and use blameless postmortems to prevent the same issues from disrupting services again:
Incident Detection and Alerting
It involves identifying unusual system behavior before it causes widespread disruption. Teams monitor application errors, latency spikes, failed transactions, and infrastructure health using tools such as Prometheus, Grafana, and Datadog. Well-configured alerts notify engineers when specific reliability thresholds are breached, reducing unnecessary notifications and speeding up investigation.
Incident Response and Escalation
When a production incident occurs, the response team focuses first on restoring service and limiting customer impact. Engineers follow established runbooks, assign incident ownership, communicate updates to stakeholders, and involve specialized teams when needed. Clear escalation procedures prevent delays during critical failures and help restore normal operations efficiently.
Root Cause Analysis (RCA)
RCA examines why an incident happened and what allowed it to affect the system. Software engineers review application logs, deployment histories, infrastructure changes, and dependency failures to uncover contributing factors. The findings guide targeted fixes that address underlying problems instead of repeatedly treating the same symptoms.
Post-incident Reviews and Blameless Postmortems
After an incident, teams reconstruct the event timeline, document customer impact, and evaluate how detection and recovery could have been faster. Blameless postmortems focus on scalable system weaknesses rather than individual mistakes. Each review should produce actionable improvements, assigned owners, and deadlines to ensure lessons translate into meaningful changes.
Continuous Incident Prevention
Preventing recurring incidents requires turning investigation findings into permanent engineering improvements. Teams may introduce automated rollback mechanisms, expand test coverage, improve dependency monitoring, or eliminate single points of failure. Reviewing incident trends and verifying completed corrective actions helps organizations reduce repeat outages and build more resilient production systems.
Automation and Self-healing Infrastructure in SRE
Here’s how SRE uses automation and self-healing mechanisms to detect failures, restart unhealthy services, scale resources dynamically, and reduce manual intervention before minor issues escalate into major outages:
Automated Incident Remediation
When a service crashes or a queue becomes overloaded, automated remediation can trigger predefined recovery actions. For example, scripts can restart failed processes, clear stuck jobs, or replace unhealthy cloud instances, reducing recovery time without requiring engineers to handle every repetitive incident manually.
Self-healing Systems
Self-healing infrastructure detects component failures and automatically restores the desired system state. In Kubernetes, failed containers can be restarted and unhealthy pods replaced according to configured policies. These mechanisms help applications recover from routine failures while alerting engineers when automated recovery cannot resolve the underlying issue.
Infrastructure Monitoring and Observability
Combining metrics, logs, and distributed traces helps engineers connect infrastructure problems with application failures. For example, rising API latency can be traced to database connection exhaustion or a slow downstream service. This context speeds troubleshooting and helps teams identify the root cause of degradation.
Automated Deployment and Rollbacks
Deployment automation reduces release-related incidents by applying consistent checks throughout the delivery pipeline. Canary deployments expose changes to a small percentage of traffic first, while automated rollback mechanisms can revert a release when error rates increase or latency exceeds predefined thresholds.
Predictive Maintenance
Predictive maintenance uses historical telemetry and workload trends to spot warning signs before infrastructure fails. For instance, forecasting disk exhaustion can trigger capacity expansion before applications run out of storage. Proactive checks on certificate expiry, memory growth, and database capacity also reduce preventable production incidents.
Key SRE Metrics and Best Practices
Explore the SRE metrics that matter most, from SLIs and SLOs to error budgets & MTTR, and learn how teams use them to track reliability, prioritize fixes, and make informed operational decisions:
Service Level Indicators (SLIs)
SLIs give SRE teams a measurable view of how a service performs for real users. Instead of relying on server health alone, teams track request success rates, response times, and failed transactions to identify problems that directly affect the user experience.
Service Level Objectives (SLOs)
SLOs turn reliability expectations into specific, measurable targets. For example, an e-commerce platform might target 99.95% successful checkout requests each month. When performance falls below this target, SRE teams can prioritize fixing reliability issues before introducing changes that could further disrupt customer transactions.
Service Level Agreements (SLAs)
SLAs define the level of service customers can expect and the provider’s responsibilities when commitments are missed. For a cloud application, this could mean guaranteeing 99.9% monthly availability and providing service credits for qualifying outages. SRE teams monitor performance against these commitments to reduce business and contractual risks.
Error Budgets
Error budgets help teams decide when to prioritize product development and when to focus on reliability. If a service has a 99.9% availability SLO, its error budget allows approximately 43.2 minutes of downtime in a 30-day month. If outages consume that budget quickly, teams may pause risky releases and address recurring failures.
Toil Reduction
Toil reduction eliminates repetitive operational work that consumes engineering time without delivering lasting improvements. For example, automating routine server provisioning, log collection, and incident notifications can reduce manual effort and human error. SRE teams can then spend more time improving system architecture, deployment safety, and recovery mechanisms.
Continuous Monitoring and Improvement
Continuous monitoring helps SRE teams detect abnormal behavior before minor issues become major incidents. By combining real-time dashboards, actionable alerts, distributed tracing, and post-incident reviews, teams can identify recurring bottlenecks, investigate root causes, and validate whether corrective changes actually improve service reliability.
Popular Site Reliability Engineering Tools
Discover the SRE tools that teams use to monitor system health, track service-level objectives, automate deployments, investigate incidents, and identify performance bottlenecks across complex production environments:
Prometheus
Prometheus collects and stores time-series metrics from applications and infrastructure. Its flexible query language, PromQL, helps engineers monitor service health, configure alerting rules, and investigate performance changes.
Grafana
Grafana transforms metrics from monitoring systems into dashboards that reveal trends, bottlenecks, and service degradation. Engineers use customizable visualizations to track latency, error rates, resource utilization, and availability targets.
Datadog
Datadog provides a unified observability platform for infrastructure, applications, logs, and distributed traces. SRE teams use its dashboards, anomaly detection, and alerting capabilities to troubleshoot production issues across cloud environments.
New Relic
New Relic helps engineers monitor application performance through transaction traces, error analytics, infrastructure metrics, and real-user monitoring. It connects application behavior with underlying services, making performance bottlenecks easier to identify.
PagerDuty
PagerDuty manages incident notifications, on-call schedules, and escalation workflows. When monitoring systems detect critical failures, it alerts the responsible engineers and coordinates responses, helping teams reduce delays and restore services faster.
Kubernetes
Kubernetes orchestrates containerized applications by managing deployments, service discovery, scaling, and workload recovery. SRE teams use its health checks, replica management, and automated scheduling to maintain application availability across distributed infrastructure.
Terraform
Terraform enables teams to provision and manage cloud infrastructure through version-controlled configuration files. It supports repeatable deployments, infrastructure reviews, and consistent environments, reducing manual configuration errors across development, staging, and production systems.
Challenges of Implementing Site Reliability Engineering
Explore the common roadblocks organizations face when adopting SRE and how these challenges can affect implementation, team collaboration, and long-term reliability:
Managing Complex Infrastructure
Modern applications depend on interconnected microservices, databases, APIs, and cloud resources. A failure in one component can affect multiple services, making troubleshooting difficult. SRE teams need clear dependency mapping, centralized observability, and effective incident coordination to manage this complexity.
Balancing Reliability and Development Speed
Frequent releases help businesses deliver features faster, but poorly tested changes can introduce production failures. Teams must balance delivery speed with reliability targets by using automated testing, progressive deployments, error budgets, and rollback mechanisms without unnecessarily slowing down development.
Reducing Operational Toil
Repetitive tasks such as manual deployments, routine troubleshooting, and infrastructure provisioning consume valuable engineering time. Eliminating toil requires identifying high-frequency tasks, prioritizing automation, and maintaining reliable scripts. Poorly designed automation can introduce new failures instead of reducing operational workload.
Managing Alert Fatigue
Excessive notifications from monitoring systems can overwhelm engineers and cause critical incidents to go unnoticed. Organizations need actionable alert thresholds, proper severity classification, and alert deduplication. Regularly reviewing noisy alerts helps on-call teams focus on genuine service degradation and respond effectively.
Addressing Skill Gaps
Implementing SRE requires expertise in software engineering, distributed systems, automation, monitoring, and incident management. Teams without these skills may struggle to establish meaningful reliability objectives or automate operations effectively. Training, hands-on exercises, documentation, and collaboration help build these capabilities.
Maintaining Reliability Across Multi-cloud Environments
Running applications across AWS, Azure, and Google Cloud introduces differences in monitoring, networking, identity management, and deployment. Without standardized configurations, unified observability, and clear incident procedures, maintaining consistent reliability becomes difficult. Teams must also manage cross-cloud dependencies, security policies, and operational costs.
Partner with our experts to improve system reliability, automate operations, minimize downtime, and build resilient infrastructure that scales with your business.
How Moon Technolabs Helps Implement Site Reliability Engineering
Moon Technolabs helps businesses build reliable, scalable, and resilient software systems by combining cloud engineering, DevOps practices, and automation. As a top-notch DevOps development company, we help businesses adopt engineering practices that strengthen system reliability and simplify ongoing operations.
- Automate software builds, testing, and deployments to reduce manual errors and minimize release-related risks.
- Optimize cloud infrastructure to improve resource utilization, application availability, and scalability as workloads increase.
- Implement monitoring and observability practices to identify performance bottlenecks, detect failures, and troubleshoot issues faster.
- Automate infrastructure provisioning and configuration to keep environments consistent across development, testing, and production.
- Improve incident detection, response, and recovery workflows to reduce service disruptions and restore operations efficiently.
- Strengthen application reliability through scalable architecture, resilient deployment strategies, and continuous performance improvements.
Conclusion
Site Reliability Engineering is not just about preventing outages; it is about building systems that recover quickly, maintain consistent performance, and scale with business demands. By tracking reliability metrics, automating repetitive tasks, and learning from incidents, organizations can reduce operational risks and make better engineering decisions.
Businesses looking to strengthen these practices can hire DevOps developers to improve deployment workflows, automate infrastructure management, and establish reliable monitoring processes. Integrating these capabilities early helps prevent recurring failures, reduce maintenance overhead, and support long-term application stability.
FAQs
01
What is the main purpose of site reliability engineering?
SRE's main purpose is to improve system reliability, availability, and performance through automation and engineering practices. It balances rapid software delivery with system stability, reduces operational risks, and minimizes manual intervention.02
What is the difference between SRE and DevOps?
SRE applies software engineering principles to operations, emphasizing reliability, automation, and measurable service-level objectives. DevOps is a broader cultural and collaborative approach that improves communication between development and operations teams to deliver software faster and more reliably.03
What are the four golden signals of SRE?
The four golden signals of SRE are latency, traffic, errors, and saturation. Latency measures response time, traffic tracks demand, errors identify failed requests, and saturation indicates resource utilization. Monitoring these signals helps teams detect and resolve reliability issues.04
Which tools are commonly used in site reliability engineering?
Common SRE tools include Prometheus and Grafana for monitoring and visualization, PagerDuty for incident management, Kubernetes for container orchestration, Terraform for infrastructure automation, and Datadog for observability. These tools help teams automate operations, troubleshoot issues, and maintain reliability.05
How much does it cost to implement SRE?
The cost of implementing SRE depends on team size, infrastructure complexity, tooling, and existing processes. Small organizations may start with limited investment, while larger enterprises need substantial budgets for skilled engineers, monitoring platforms, automation, and ongoing operational improvements.


The DevOps Team at Moon Technolabs consists of experienced engineers and cloud specialists who share insights on modern software delivery and infrastructure management. With expertise in AWS, Azure, CI/CD pipelines, containerization, and cloud-native architectures, the team contributes practical knowledge drawn from real-world projects. Their content focuses on automation, scalability, cloud cost optimization, and best practices that help businesses build reliable and efficient development ecosystems.
Submitting the form below will ensure a prompt response from us.
We refine our expertise to deliver innovative business solutions.

205 N Michigan Avenue, #810, Chicago, 60601, Illinois, United States
13500 Long Is Dr, Pflugerville, TX 78660, USA

C/105 Ganesh Meridian, S.G. Highway, Ahmedabad, GJ 380060



Ayse D.
Co-Founder France
“ I highly recommend Moon Technolabs as the quality of service is wonderful. We have hired this company to develop the product based on some complex & technical issues. We get the best quality services as compared with others in the market. Huge Thanks to Moon Technolabs as the team is always ready to give the solution all time.”

Justin G.
Founder & CEO USA
“ Moon Technolabs is a pioneer in the WebRTC based project as they have fixed complicated segments of the module by fulfilling different product lines by providing 24X7 customer support. We really recommended Moon Technolabs as they are able to develop products as per the module deadline and project timeline.”

Flavio S.
Founder & Managing Director Germany
“I am happy to recommend Moon Technolabs for their app development services. They successfully developed apps for me, and I am highly satisfied with the overall outcomes. The development team has swiftly addressed the issues with responsive and effective communication to understand the requirement quickly and actively resolve the back-and-forth problems that arose...”

Jay M.
Founder & CEOUSA“Moon Technolabs is the best company that provides advanced apps and websites development services in the USA and Europe. I am a newbie to develop my app with an external team. I am really happy to work with them as I am not that much mobile apps user. Here, the team and specially the CEO of Moon Technolabs helps me to let me know about the benefits of my app to generate revenue....”


Our Offices
India
C/105 Ganesh Meridian,S.G. Highway, Ahmedabad, GJ 380060USA
205 N Michigan Avenue, #810, Chicago, 60601, Illinois, United StatesContact Information


